

Caching Strategy for High-Traffic Websites: Browser, CDN, Application and Database Layers
 September 26, 2026
 Reading time: 8 min read
 Category: Cloud Infrastructure
 1
Learn how to build a robust website caching strategy across browser, CDN, application, and database layers while managing stale data risks and invalidations.
Delivering web pages quickly and reliably under heavy traffic requires a well-structured multi-layered strategy rather than a single optimization point. As user concurrency scales, unoptimized requests hit backend infrastructure directly, increasing response latency and server workloads. Implementing a holistic website caching strategy across every layer of the technology stack allows systems to serve pre-computed responses closer to the user, drastically reducing redundant computations and resource exhaustion.
Understanding Caching Across the Modern Web Stack
Caching operates on a straightforward principle: store a copy of a rendered resource or computed query in high-speed, temporary storage so that subsequent requests for the same asset can be fulfilled instantly. However, modern system architectures rarely rely on a single cache. Instead, they employ an interconnected pipeline where data is saved, retrieved, and invalidated across multiple boundaries.
A comprehensive website caching strategy coordinates four primary architectural layers: browser, Content Delivery Network (CDN), application, and database caching. Each layer addresses a specific bottleneck in the request-response lifecycle. While edge caches prevent traffic from reaching server infrastructure entirely, application and database caches optimize computational efficiency when a request must penetrate deeper into the architecture. Balancing these layers ensures that static media, dynamic markup, and data queries are served with minimal resource overhead.
Layer 1: Browser Caching and Client-Side Storage
The browser cache represents the first line of defense in reducing latency. By storing static assets directly on the client machine, browsers can render returning visits without issuing new network requests for unchanged files. This layer relies heavily on HTTP headers negotiated between the web server and the user agent.
Key directives govern how client storage behaves:
Cache-Control Directives: Headers such as max-age specify the duration for which a resource remains fresh, while public or private determine whether intermediary proxies can store the content. Directives like no-cache require validation with the origin server before reuse, and no-store prevents sensitive data from being saved entirely.
Validation Headers (ETags and Last-Modified): When a cached item expires, the browser uses entity tags (ETags) or time stamps to check if the file has actually changed. If unchanged, the server returns a 304 Not Modified status code without re-transmitting the payload body.
Service Workers: Modern progressive web applications leverage service worker scripts to implement programmatically controlled caching strategies, such as Cache-First or Stale-While-Revalidate pattern flows.
While client-side storage reduces bandwidth and provides near-instantaneous page loads for returning visitors, developers lose direct, real-time control once a resource is saved on a user's device. If long cache lifetimes are set without aggressive asset versioning (such as file hash naming), updating client-side scripts or stylesheets across active user sessions becomes challenging.
Layer 2: CDN and Edge Caching
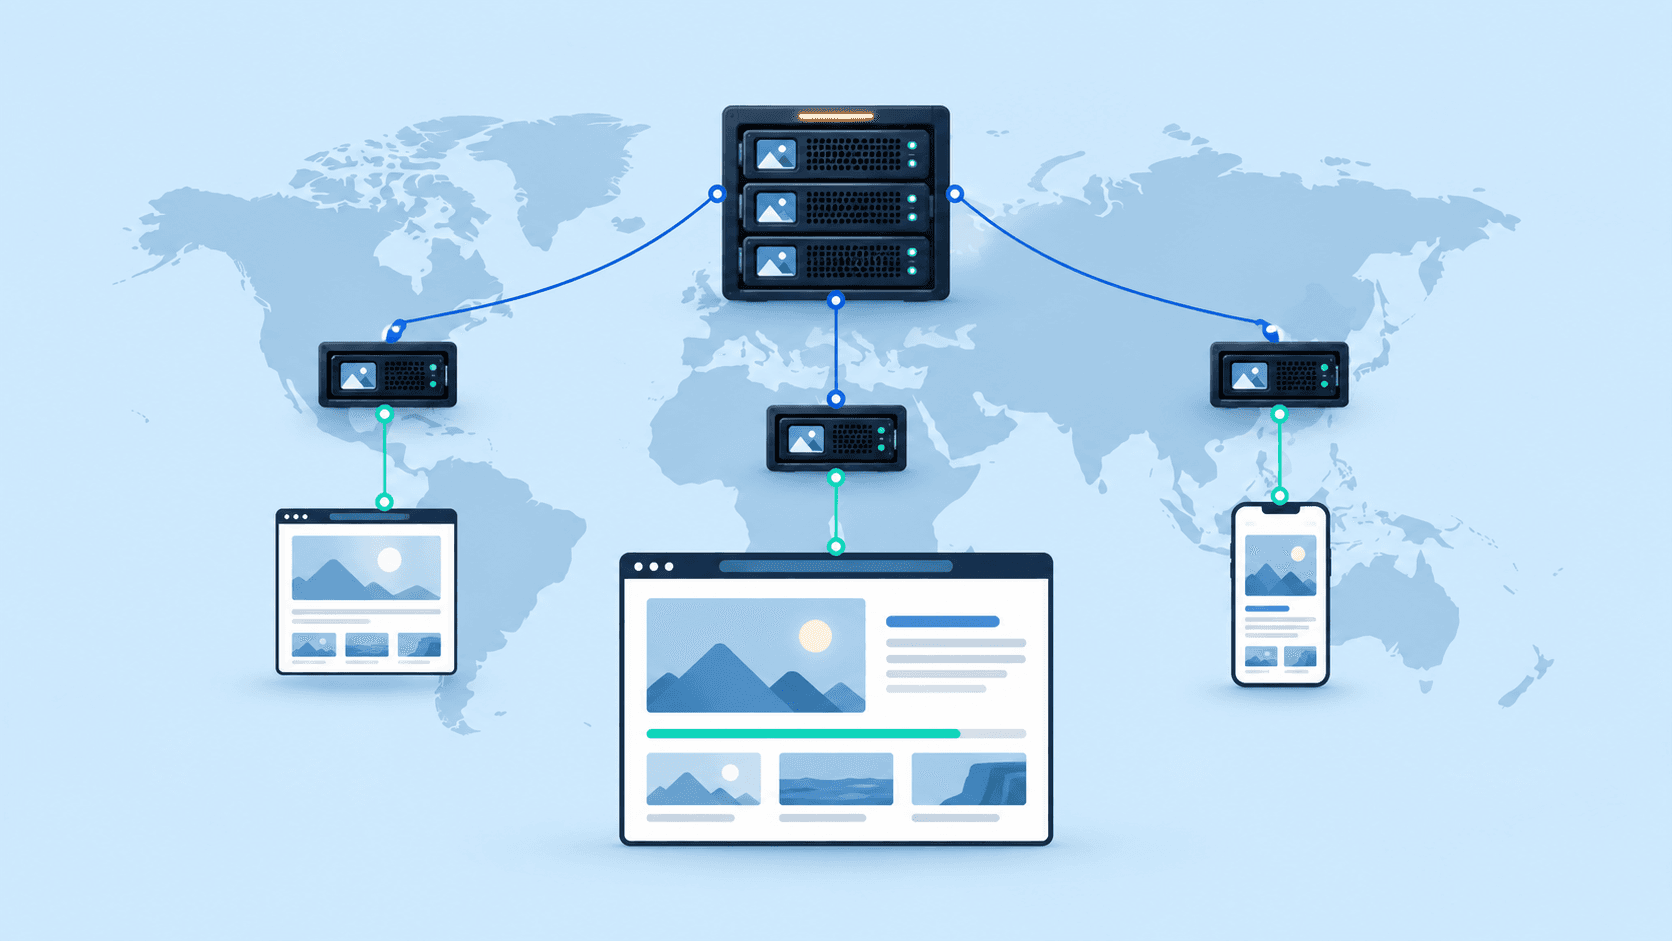
Content Delivery Networks distribute static and dynamic web content across geographically dispersed point-of-presence (PoP) servers. Edge caching intercepts user requests before they hit the origin server, drastically reducing latency by serving content from the closest geographic node.
In addition to serving static media, modern edge platforms support dynamic edge rendering and page-level caching for content that does not vary per user. custom ecommerce development By integrating intelligently designed edge rules into architectural frameworks, digital teams ensure high-traffic nodes serve cached HTML pages while passing authenticated state requests downstream seamlessly.
The main trade-off at the CDN layer centers on cache hit ratios versus cache invalidation complexity. While edge nodes absorb immense traffic spikes, purging global cache nodes during critical content updates requires clear invalidation pipelines or granular tag-based purging mechanisms to prevent serving outdated information to localized markets.
Layer 3: Application Caching and In-Memory Data Stores
When requests bypass client and edge caches to hit backend servers, application-level caching prevents costly re-computations of business logic and HTML rendering. Application frameworks often use key-value in-memory data stores to hold calculated objects, parsed templates, session states, and API responses.
Common Application Caching Patterns
Designing effective application caching involves selecting access patterns aligned with workload characteristics:
Cache-Aside (Lazy Loading): The application attempts to read from the cache first. If a cache miss occurs, it queries the database, writes the result to the cache for future requests, and returns the response. This prevents populating the cache with unused data, but initial misses incur latency penalties.
Write-Through: The application writes data to the cache and the database simultaneously. This ensures high data consistency and prevents stale reads, though write operations experience higher latency.
Write-Behind (Write-Back): Data is written directly to the cache, which acknowledges the update immediately. The cache asynchronously flushes changes to the persistent database. This optimizes write performance but introduces data loss risks if the cache node fails before persistence completes.
In-memory stores operate under memory capacity limits. Consequently, system architects must configure eviction policies—such as Least Recently Used (LRU) or Least Frequently Used (LFU)—to drop non-essential keys when memory consumption reaches threshold limits.
Layer 4: Database Caching and Buffer Pools
The database tier is frequently the hardest layer to scale horizontally under high traffic. Database caching works at both the database management system (DBMS) level and through dedicated query caching layers to minimize disk I/O operations.
Modern relational databases automatically maintain internal buffer pools and shared memory areas to keep index pages and frequently read rows resident in RAM. Beyond native buffer management, caching complex SQL query results or persistent schema definitions prevents CPU-bound parsing operations on recurring read patterns.
However, relying heavily on query-level result caches brings risks. Highly dynamic tables with frequent write, update, or delete operations constantly invalidate related query cache entries. If invalidations occur faster than hits, maintain processing overhead can outweigh the benefits of caching at this layer. For write-heavy workloads, tuning indexes and connection pools often yields better durability and throughput than aggressive database query caching.
Cache Invalidation Strategies and Stale Data Risks
As Phil Karlton famously noted, cache invalidation is one of the hardest challenges in computer science. Maintaining data consistency across browser, edge, application, and database layers requires robust synchronization mechanisms.
System architects generally choose between time-based and event-driven invalidation approaches:
Time-To-Live (TTL): Assigns an explicit expiration time to cached items. Once the TTL lapses, the next request triggers a refresh. While simple to implement, short TTLs increase origin load, whereas long TTLs expose users to stale data.
Event-Driven Purging: Emits invalidation messages across edge and application caches immediately when underlying data changes. Techniques like Cache Tagging (or Surrogate Keys) group related cached objects, allowing mass invalidation when a single product or entity is updated.
Stale-While-Revalidate: Serves stale content from the cache immediately while asynchronously fetching the updated resource in the background. This guarantees quick response times, though users may view content one revision behind until the revalidation finishes.
Failing to handle invalidation correctly leads to severe business risks: customers viewing outdated pricing or inventory status, logged-in users seeing leaked session data, or conflicting script versions breaking user interfaces. System designs must treat cache consistency as a explicit constraint rather than an afterthought.
Evaluating Strategy Trade-Offs and System Architecture
A successful website caching strategy is never an all-or-nothing implementation; it is a series of engineering decisions tailored to specific data access patterns. Static marketing sites can rely heavily on edge caching, whereas personalized transactional platforms demand tight coordination between in-memory application caches and controlled client-side storage.
Architects must evaluate trade-offs along three main dimensions:
Data Freshness vs. System Throughput: High concurrency limits require accepting minor data latency or implementing complex real-time cache purge systems.
Memory Footprint vs. Infrastructure Costs: Holding massive datasets in high-speed RAM scales performance but increases infrastructure expenditures linearly.
System Complexity vs. Maintainability: Adding multiple caching tiers creates more point-to-point dependencies, making debugging and tracing state anomalies significantly more complex.
Summary of Key Execution Steps
Building a resilient multi-layer strategy requires structured implementation. Digital engineering teams should focus on auditing and aligning every layer of their architecture:
Audit client headers to ensure static assets use far-future cache directives alongside content-hashed file names.
Configure edge rules to cache non-personalized HTML fragments and static media close to end users globally.
Implement clear application patterns like Cache-Aside using dedicated in-memory key-value stores for heavy business objects.
Establish event-driven cache invalidation patterns utilizing cache tags to keep distributed layers synchronized instantly.
Monitor cache hit-to-miss ratios, memory consumption, and origin egress traffic continuously to refine eviction policies.
Frequently Asked Questions
What is the difference between client-side caching and CDN caching?
Client-side caching stores assets directly inside the user's web browser, completely eliminating network requests for cached files on subsequent visits. CDN caching stores assets on distributed edge servers worldwide, intercepting user requests before they reach the main origin server to significantly reduce travel distance and origin server load.
How do cache tags simplify complex invalidation?
Cache tags (or surrogate keys) allow developers to assign one or more categorical identifiers to cached objects or HTTP responses. When an entity changes—such as a single product—the application fires an invalidation command targeting that tag, instantly purging every cached page or API payload associated with that identifier across the global edge network.
What are the risks of using long TTLs for dynamic content?
Using long TTLs on dynamic content increases the risk of serving stale or inaccurate data, such as outdated inventory, incorrect pricing, or stale news headlines. If a rapid data change occurs, system administrators must manually trigger forced cache purges across all layers to regain data consistency.
When should an application use Cache-Aside versus Write-Through caching?
Cache-Aside is ideal for read-heavy workloads where data requests are unpredictable, as it populates the cache only when items are requested. Write-Through is preferable when high data consistency is mandatory between the cache and underlying database, or when newly written data is guaranteed to be read immediately after creation.